y <-c(seeded, unseeded)# 52 observed daily rainfalls n <-length(y)# 52 days n_treat <-length(seeded)# 26 seeded days
t_obs <- mean(seeded)- mean(unseeded)
B <- 1000 t_sim <- numeric(B)
for(b inseq_len(B)){ treated <- sample.int(n, n_treat)# random assignment of 26 of 52 days t_sim[b]<- mean(y[treated])- mean(y[-treated]) }
p <- mean(abs(t_sim)>=abs(t_obs))
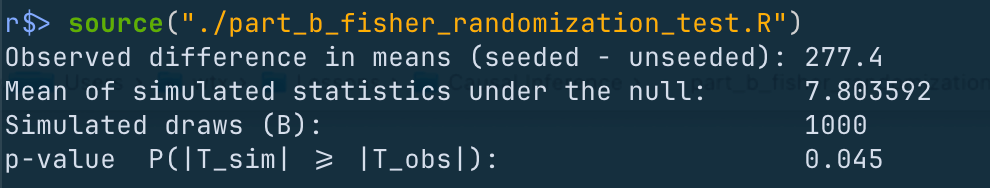
cat("Observed difference in means (seeded - unseeded):", t_obs,"\n") cat("Mean of simulated statistics under the null: ", mean(t_sim),"\n") cat("Simulated draws (B): ", B,"\n") cat("p-value P(|T_sim| >= |T_obs|): ", p,"\n")
Run results follow:
c.
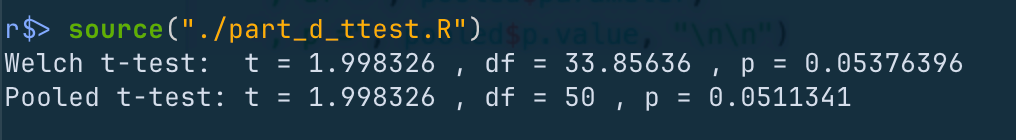
The variance of our estimated p-value is 1000p(1−p) where p is the real p-value. One upper bound for the large-sample standard error is 210001≈0.0158, which is on the same order of magnitude as the p-value we just estimated. So I would say the simulation is not very accurate.
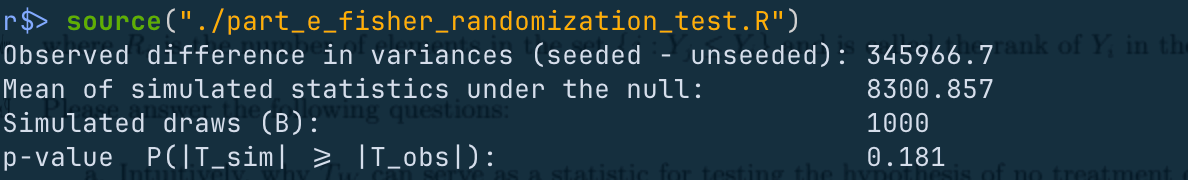
Replace the code in part (b) t_obs <- mean(seeded) - mean(unseeded) with t_obs <- var(seeded) - var(unseeded). The results are
f.
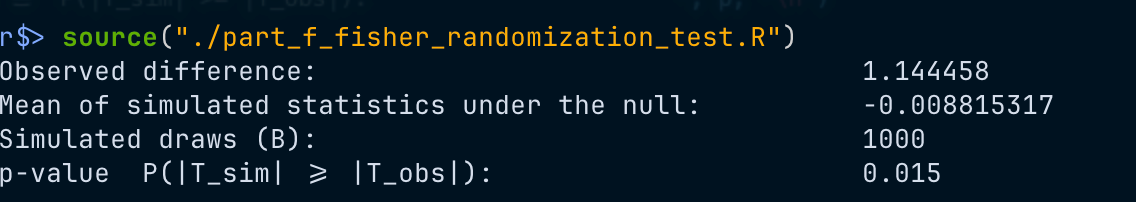
Replace the code in part (b) t_obs <- mean(seeded) - mean(unseeded) with t_obs <- mean(log(seeded)) - mean(log(unseeded)). The results are
g.
Test statistic corresponding to the true model has more power.
Problem 2 (Another test statistic for Fisher’s test)
a.
First, it can be computed with the data at hand. Second, the statistic is sensitive to the null hypothesis because when it doesn't hold, the statistic is more likely to be larger or smaller compared to when it holds. Units that receive the treatment are more likely to rank higher or lower when there is treatment effect.
y <-c(seeded, unseeded)# 52 observed daily rainfalls r <- rank(y) n <-length(y)# 52 days n_treat <-length(seeded)# 26 seeded days
t_obs <-sum(r[1:26])- n_treat*(n+1)/2
B <- 1000 t_sim <- numeric(B)
for(b inseq_len(B)){ treated <- sample.int(n, n_treat)# random assignment of 26 of 52 days t_sim[b]<-sum(r[treated])- n_treat*(n+1)/2 }
p <- mean(abs(t_sim)>=abs(t_obs))
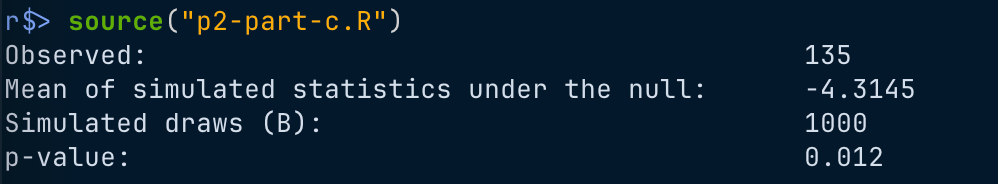
cat("Observed: ", t_obs,"\n") cat("Mean of simulated statistics under the null: ", mean(t_sim),"\n") cat("Simulated draws (B): ", B,"\n") cat("p-value: ", p,"\n")
The results are
d.
z=V(TW)TW−E(TW)=54.64135=2.47, the p-value is Φ(−2.47)+(1−Φ(2.47))=0.0135
e.
Wilcoxon statistic is more robust to extreme values.
Problem 3
1.
Unit
Di
Di−1
Yi(1,1)
Yi(1,0)
Yi(0,1)
Yi(0,0)
1
1
1
4%
2
1
1
2%
3
0
1
8%
4
1
0
9%
5
0
1
12%
6
0
0
13%
7
0
0
4%
8
1
0
1%
2.
(i)
The estimand: Yˉ(1,1)−Yˉ(0,1).
The estimator: ∑DiDi−1∑DiDi−1Yi−∑(1−Di)Di−1∑(1−Di)Di−1Yi=−7%
(ii)
The estimand: Yˉ(1,0)−Yˉ(0,0).
The estimator: ∑Di(1−Di−1)∑Di(1−Di−1)Yi−∑(1−Di)(1−Di−1)∑(1−Di)(1−Di−1)Yi=−3.5%
(iii)
The estimand: [Yˉ(1,1)−Yˉ(0,1)]−[Yˉ(1,0)−Yˉ(0,0)].
The estimator: ∑DiDi−1∑DiDi−1Yi−∑(1−Di)Di−1∑(1−Di)Di−1Yi−[∑Di(1−Di−1)∑Di(1−Di−1)Yi−∑(1−Di)(1−Di−1)∑(1−Di)(1−Di−1)Yi]=−3.5%
Problem 4
1.
δ1=δ2:
Y(1)=[1,1,1], Y(0)=[1,1,1]
δ1>δ2:
Y(1)=[1,100,101], Y(0)=[4,5,11]
δ1<δ2:
Y(1)=[1,100,110], Y(0)=[−100,5,6]
2.
I think δ2 makes more sense because it represents the effect on a single unit while δ1 represents the difference between two populations.
Problem 5
1.
Question: Does taking a structured online course (vs. self-studying with free resources) improve students' exam scores in an introductory statistics class?
Unit: Individual students enrolled in the course.
Actions: Treatment = enroll in the structured online course; Control = self-study using free online materials.
Potential Outcomes:Yi(1) = exam score if student i takes the course; Yi(0) = exam score if student i self-studies.
Covariates: Prior GPA, math background, weekly study hours, whether the student works part-time.
2.
Partially reasonable. No-interference is plausible if students study independently, but could be violated if students discuss course content or study together, letting one student's treatment affect another's outcome. The "no hidden variations of treatment" part is also questionable, since course quality and self-study resource quality can vary across students.
3.
Recruit a pool of students planning to take intro statistics. Randomly assign half to the online course and half to self-study, controlling access to materials. Collect baseline covariates via a pre-survey, then record final exam scores for all participants.
4.
Since assignment is done by the researcher, this would be data from a randomized experiment, not an observational study — assuming compliance is enforced and randomization is properly implemented.